The Centaur blog
Research, results, and customer stories.
Latest article
Health AI evaluation
CLEAR-Bench: Where LLMs fall short on handling health questions safely
Comparing crowd preferences with clinician and model-judge reviews of health responses.
Read article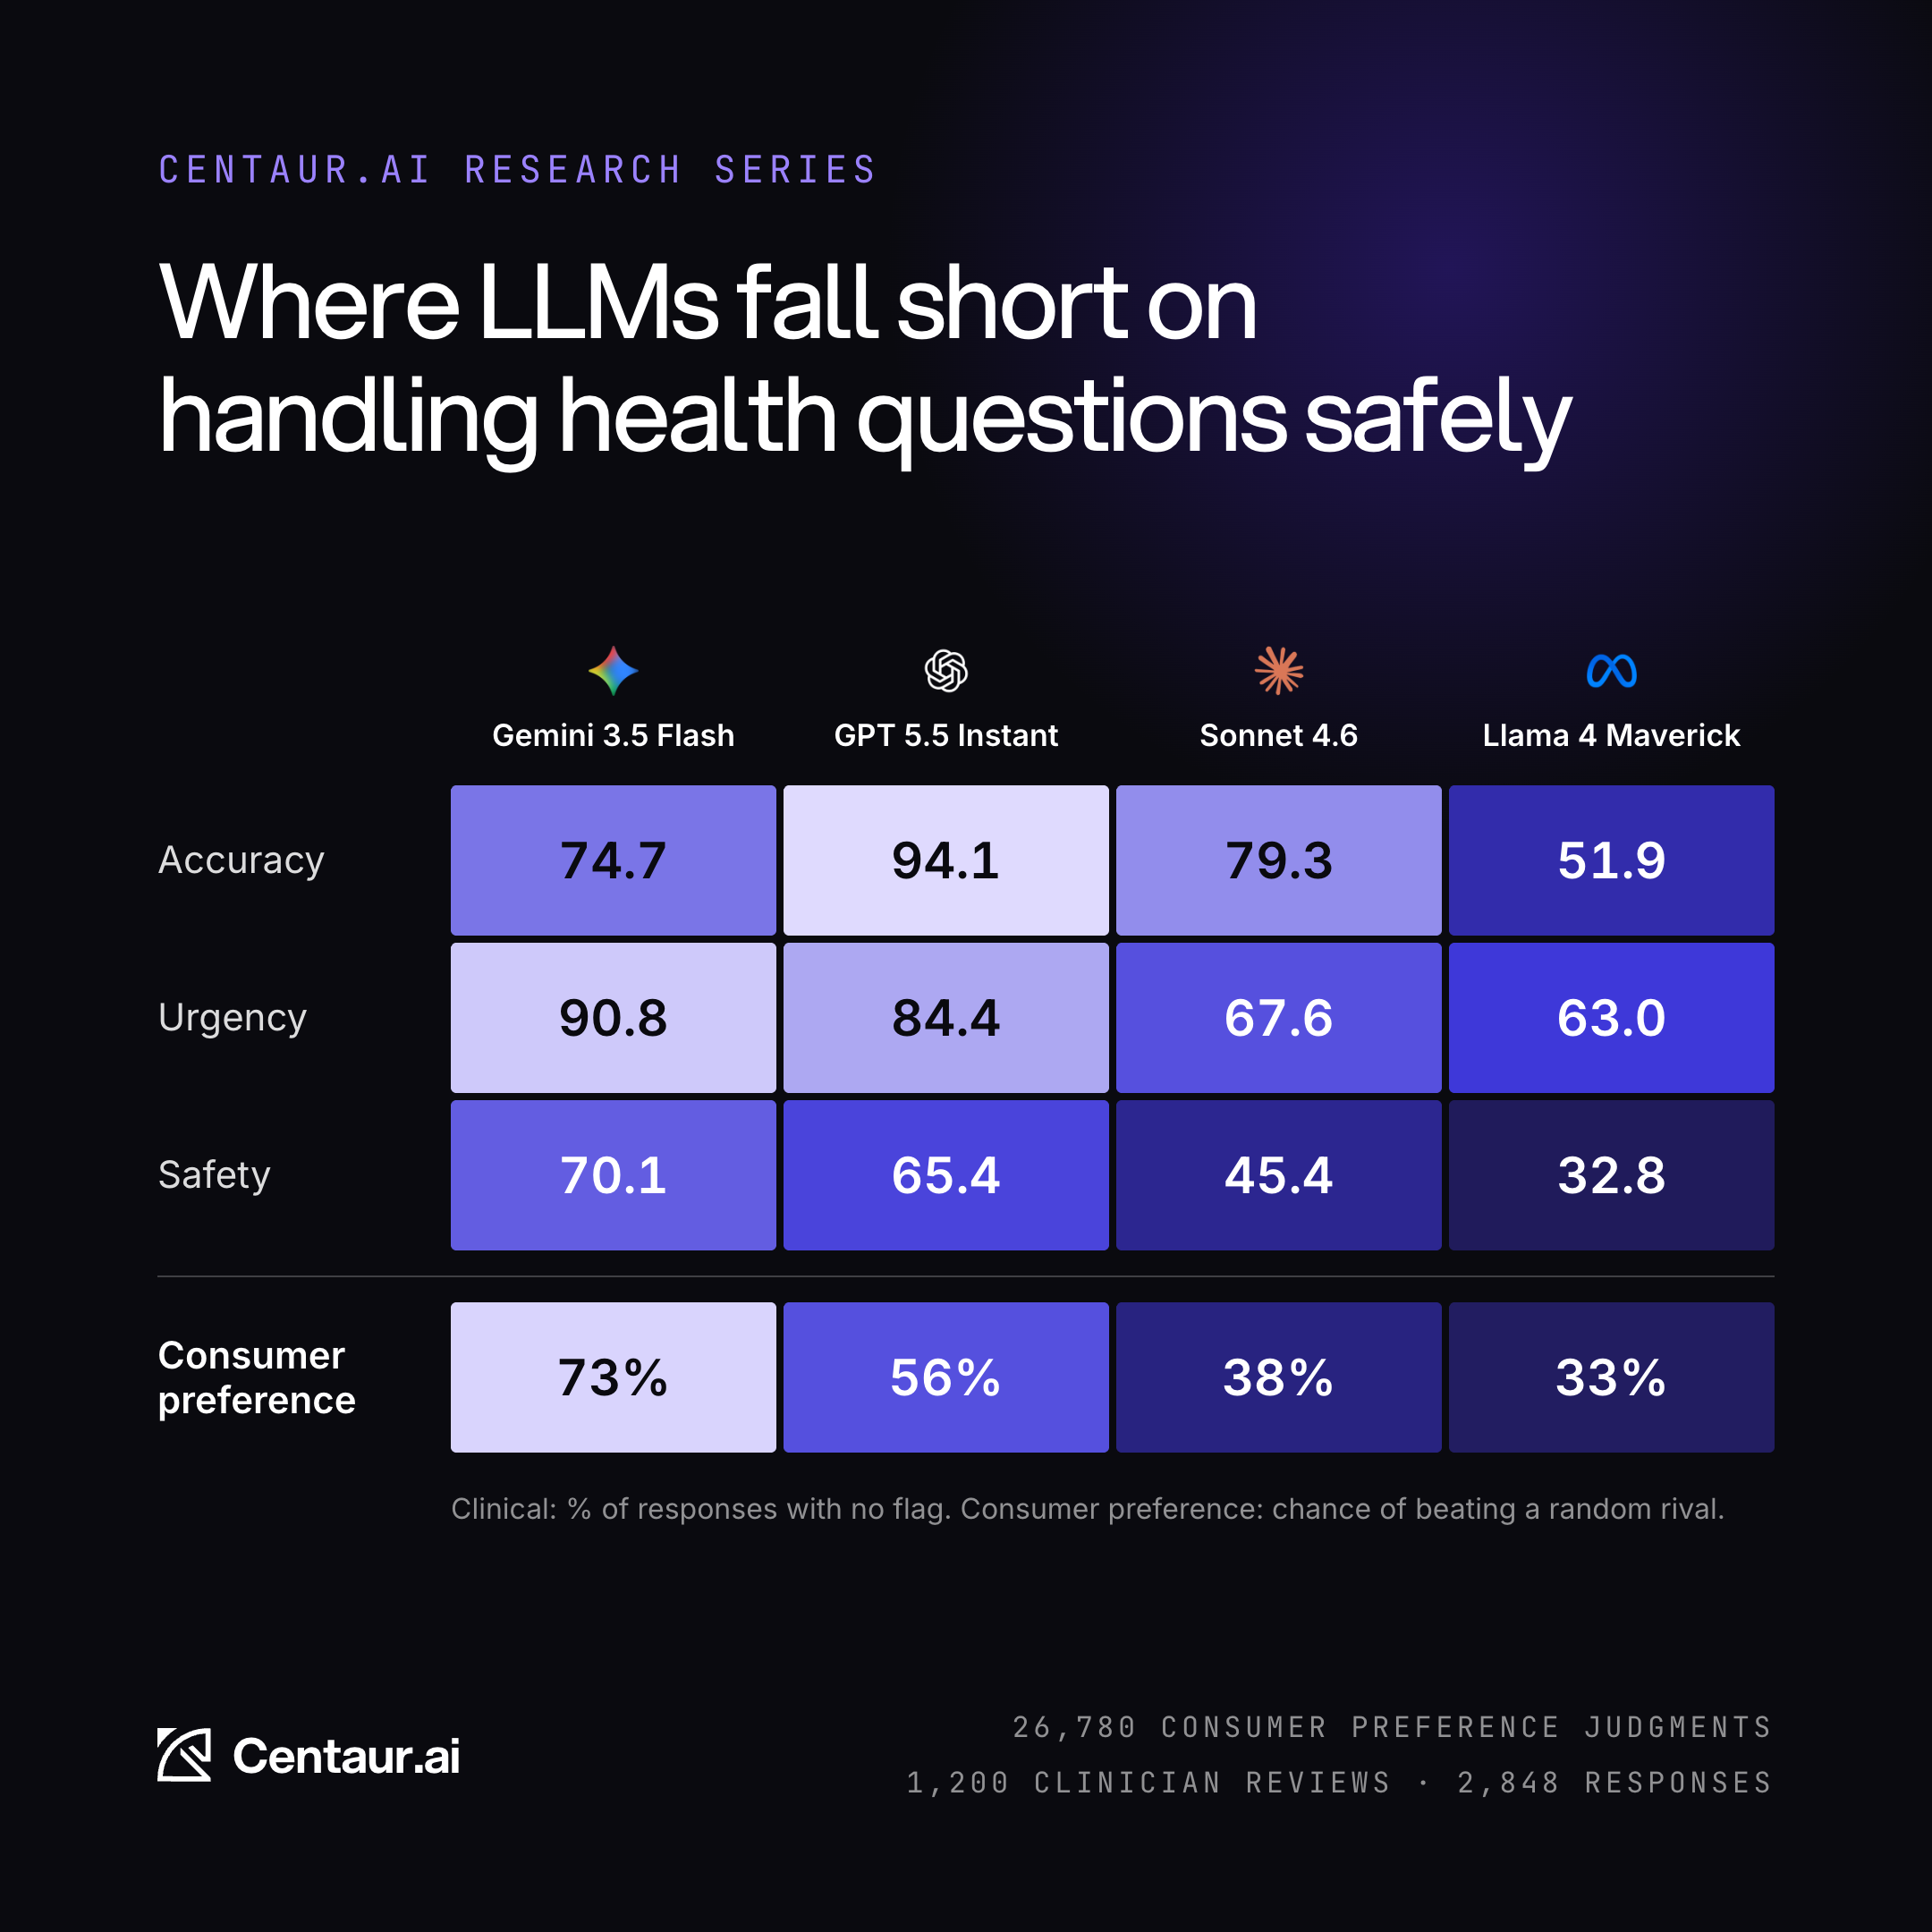
More articles
Research note
Multi-Turn Healthcare Evaluation Research Note
An evaluation in development: how assistants update, retract, and retain information across a conversation.
The Limits of Preference · 02
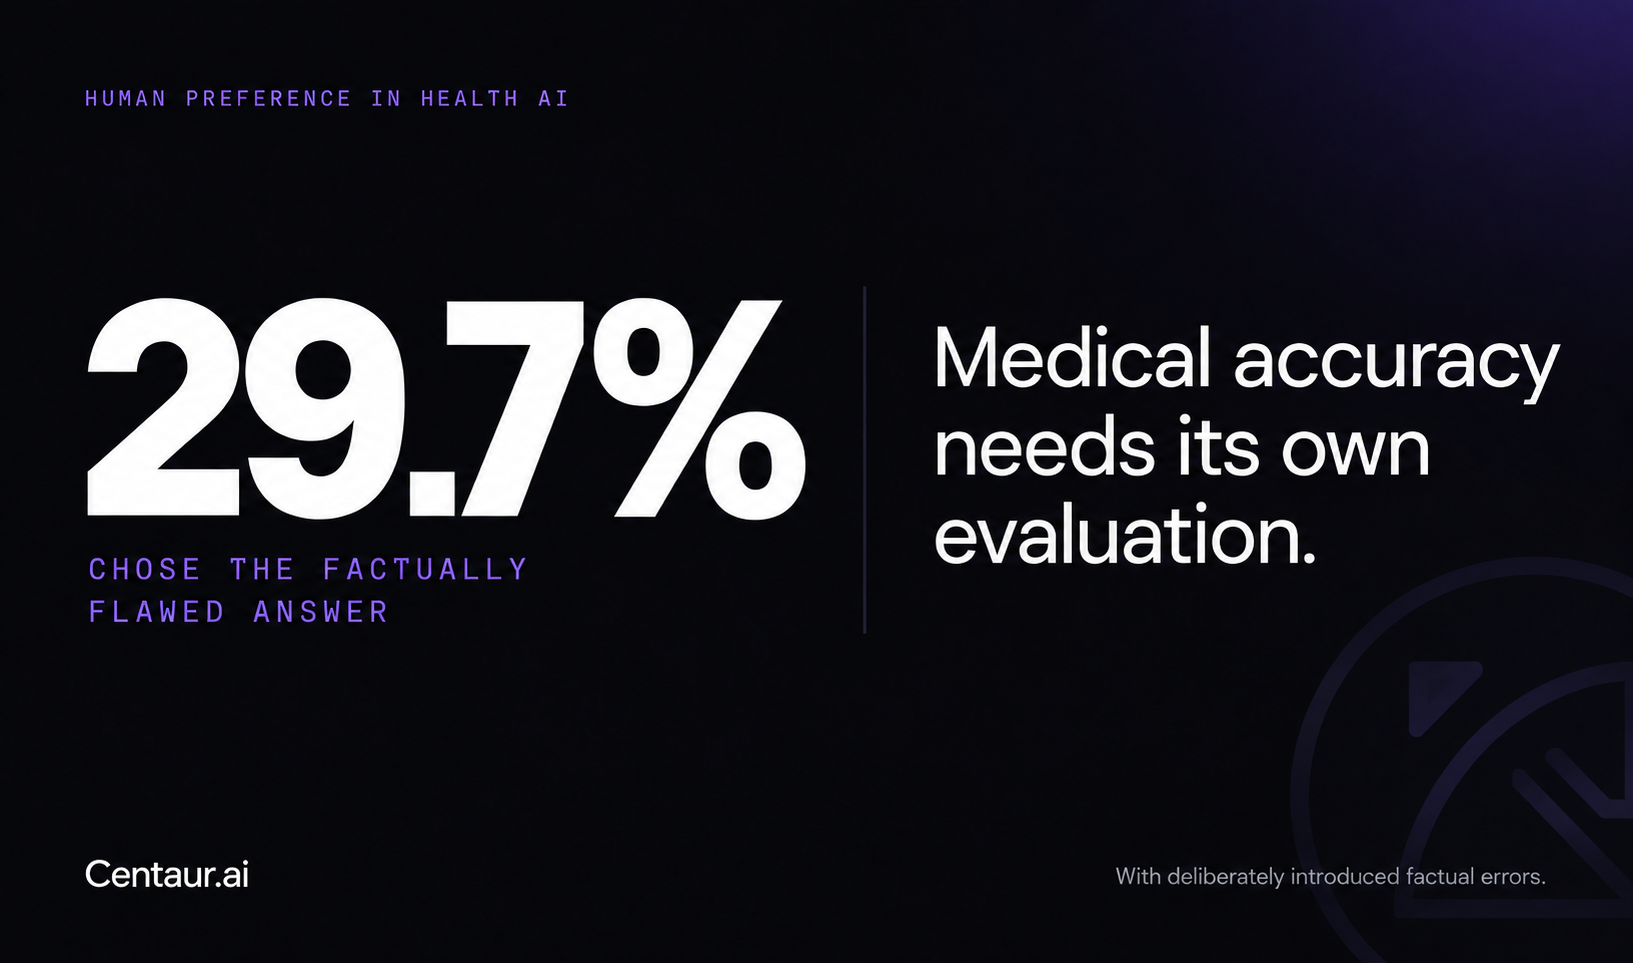
What a Preference Score Can Miss In a Health Response
Why a preferred answer can still contain a medical error.
Arena results
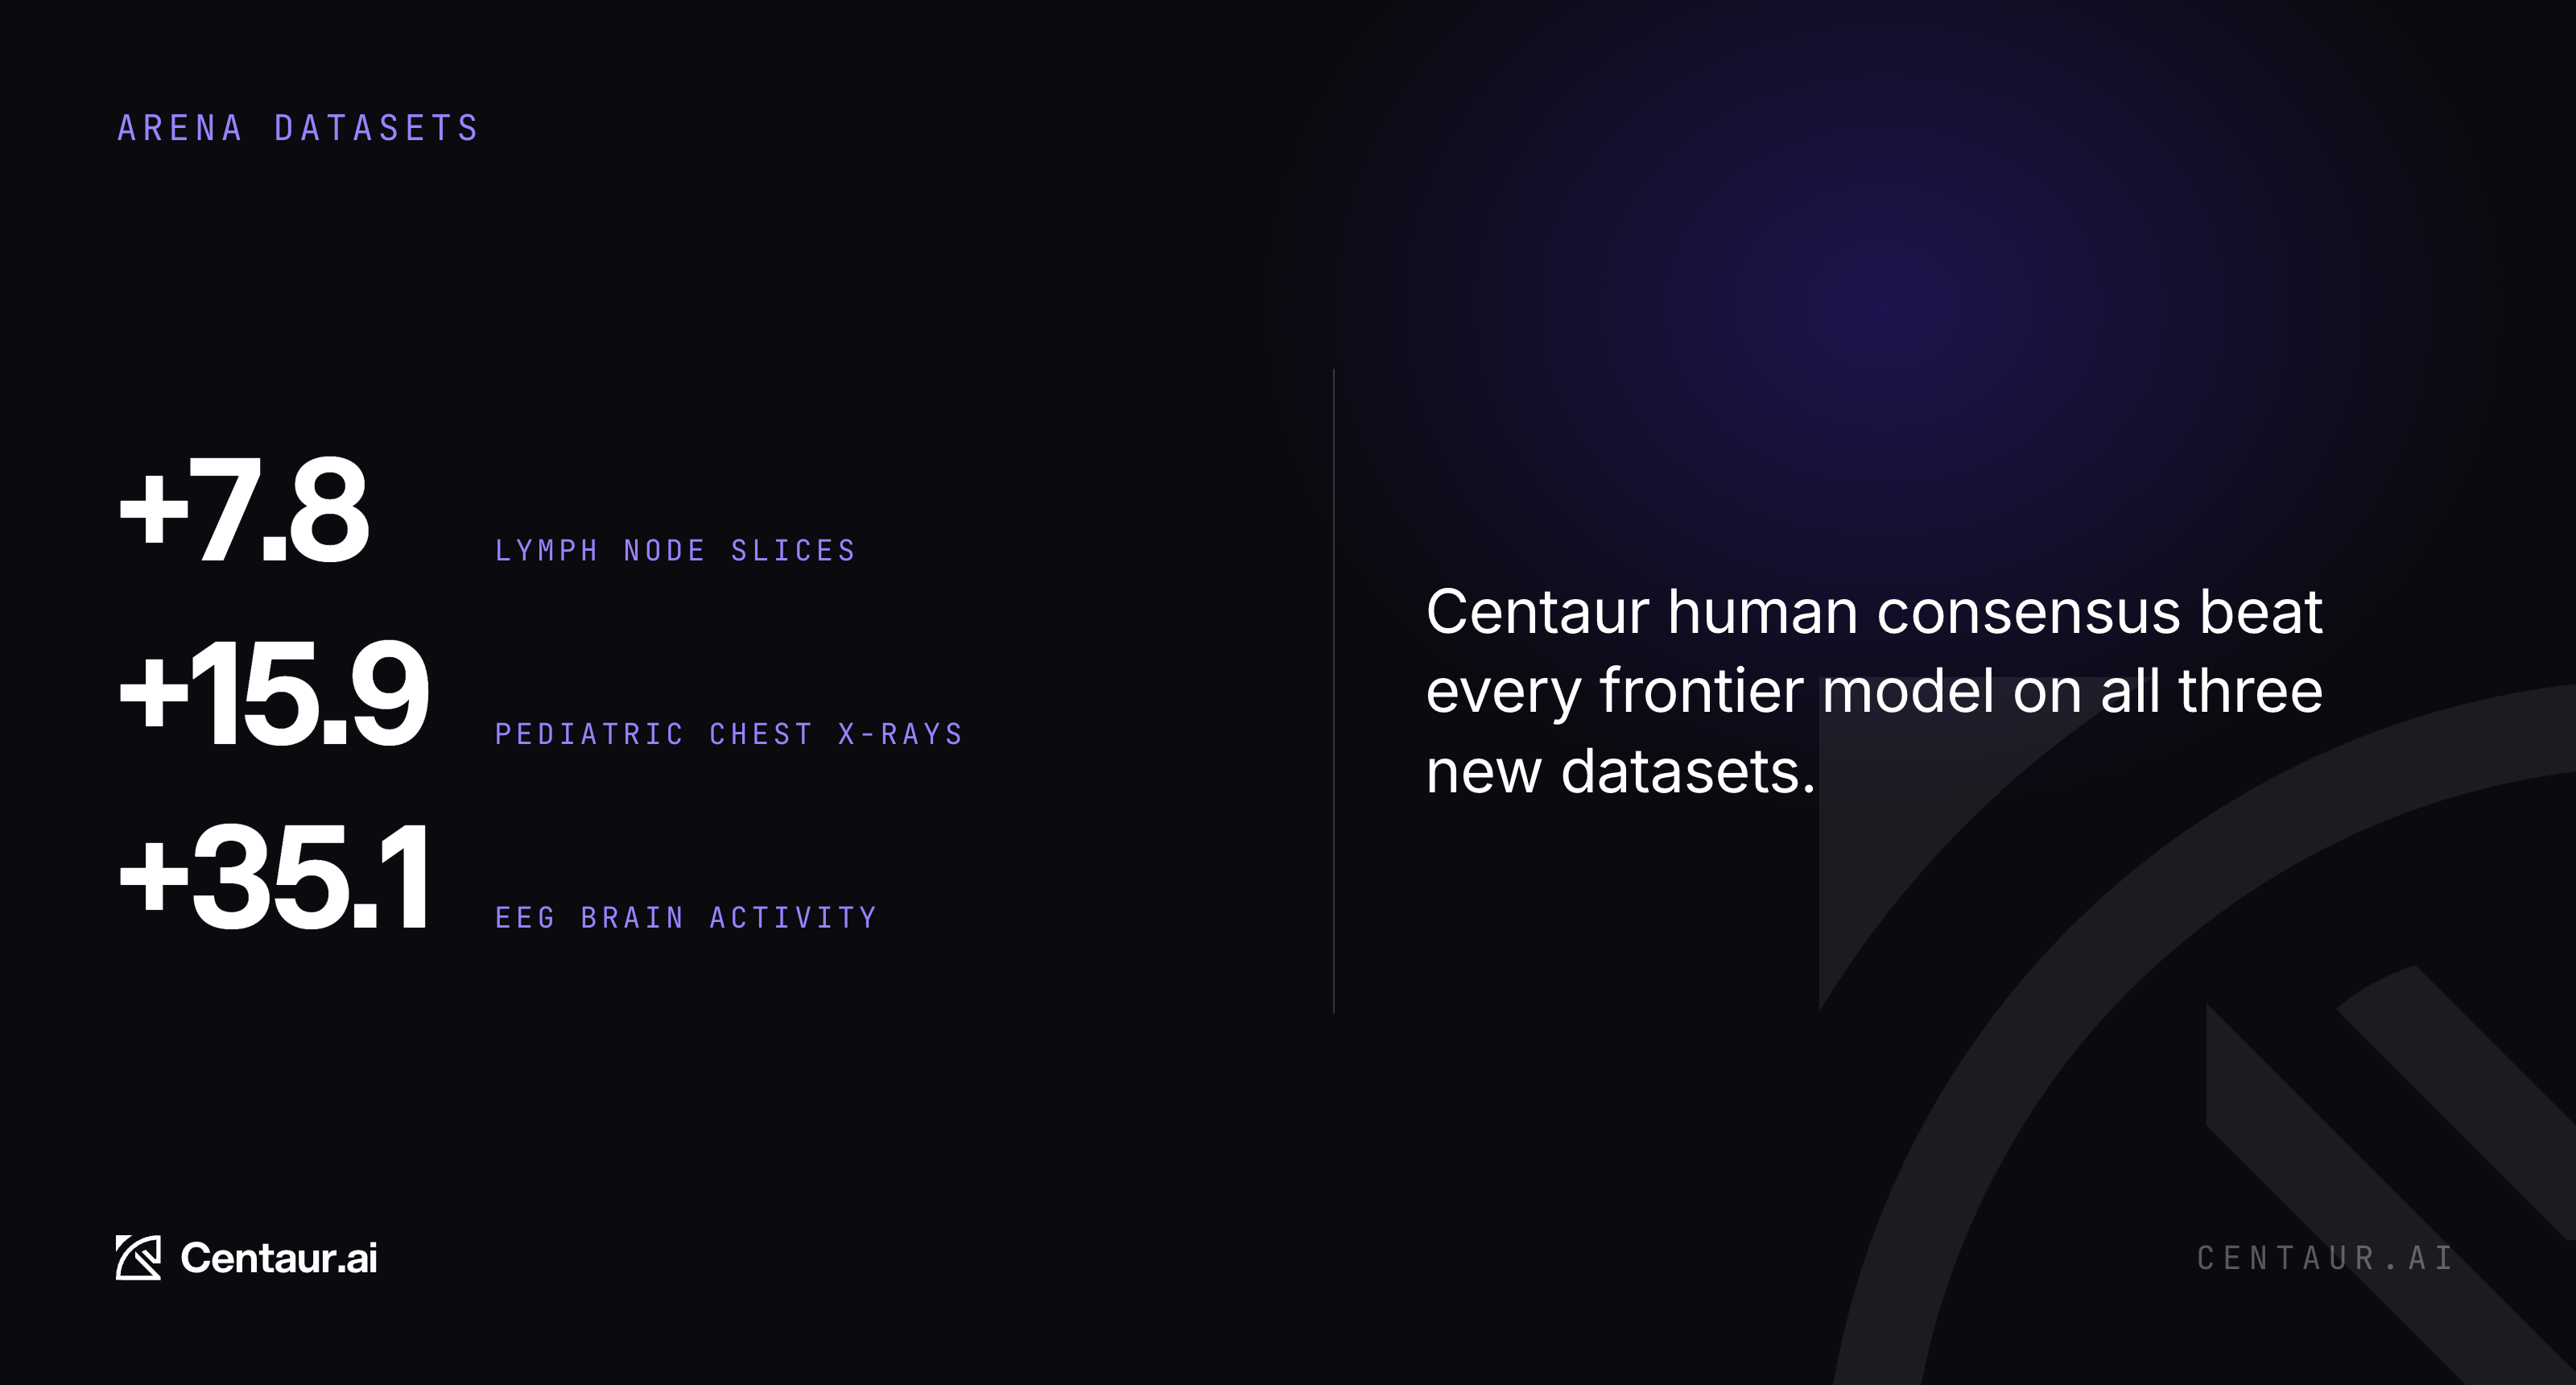
3 New Datasets Added to Centaur’s Arena
Published results for tissue classification, pediatric chest X-rays, and EEG annotation.
Customer story
Case Study: Centaur and Median Technologies
Supporting FDA 510(k) Clearance and Class IIb CE Marking for eyonis® LCS
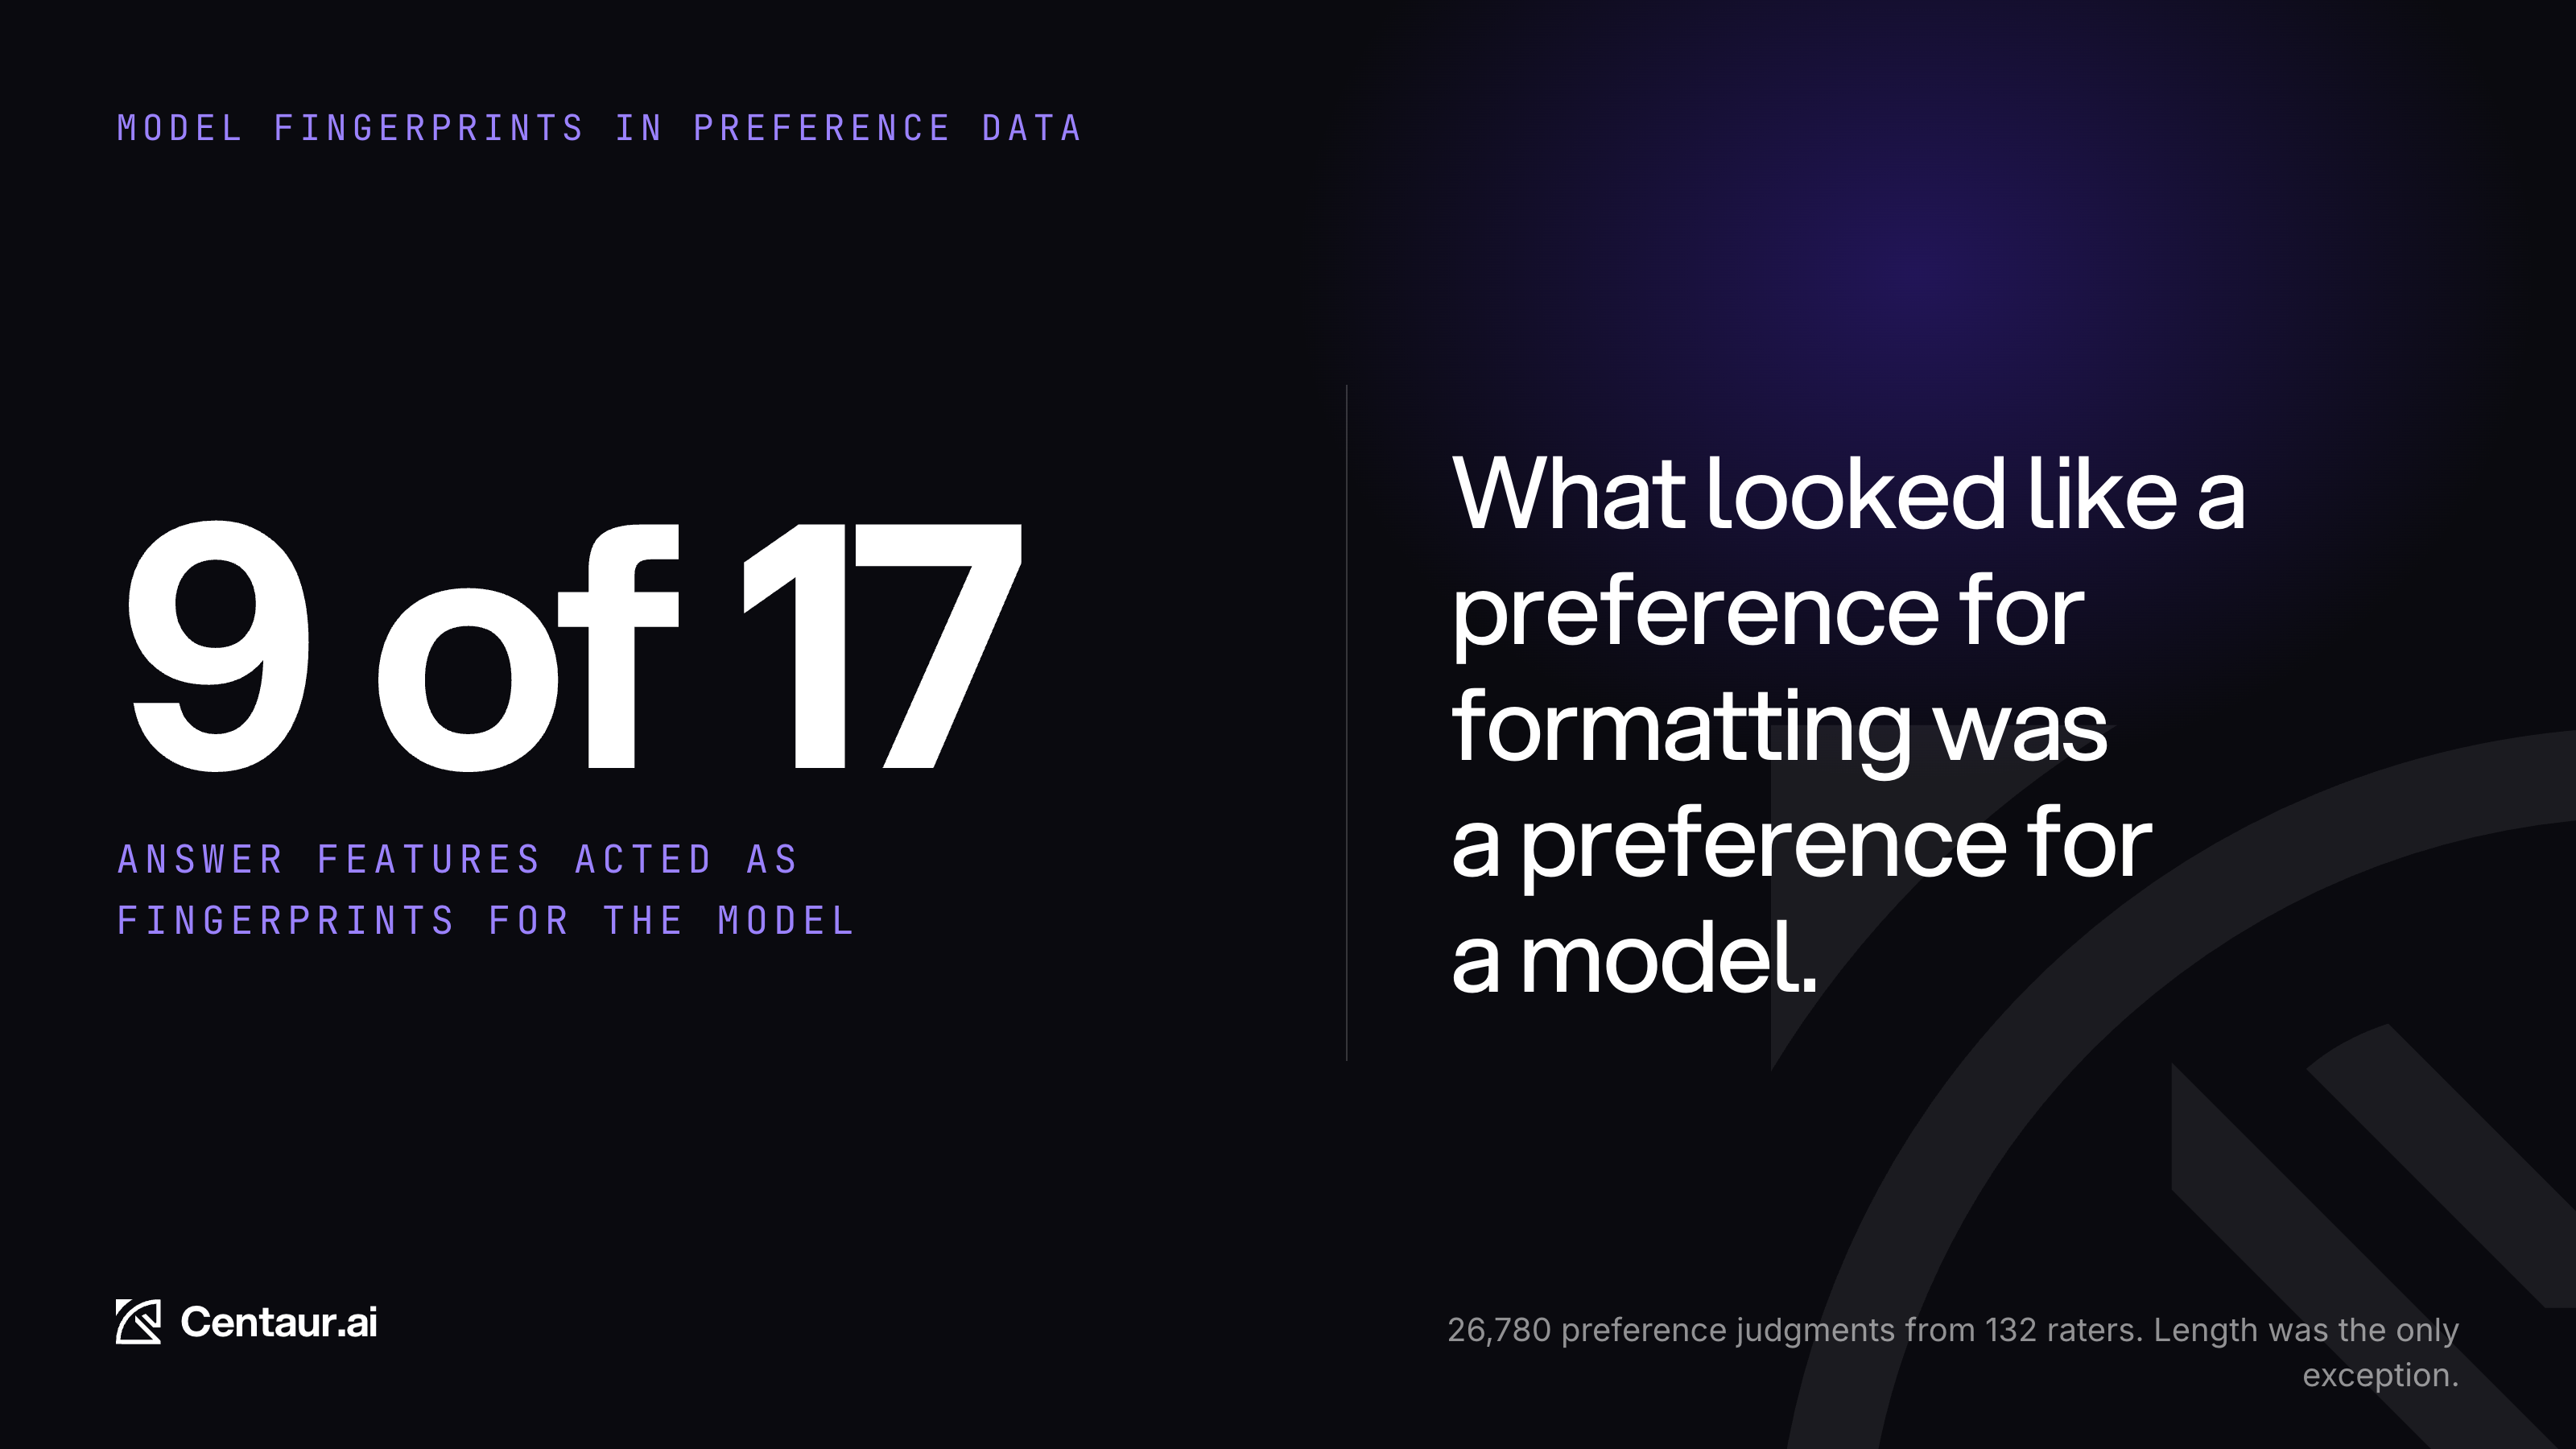
The Limits of Preference · 01
When Answer Features Become Model Fingerprints
Separating response features from the writing habits of individual models.
Research & insights
How Does Grok 4.5 Handle Real Health Questions? We Tested 712 Questions With a Clinician Rubric
We tested Grok 4.5 with 712 real health questions and checked each answer in three ways: did it react to the danger level correctly, was it safe to follow, and was the medical information correct?
Arena results
Calorie Estimation Benchmark
How Centaur’s annotators and AI models compare on estimating the calories in meal images.